 AI Generated Apps AI Code Learning Technology
Related Articles

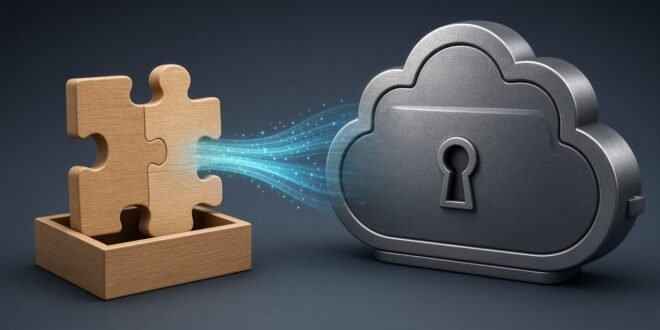
The internet loves tribal fights: open forever versus closed APIs. Operators need a calmer frame. This open-weight vs closed models guide gives a per-workload decision framework for 2027.

Open weights

Closed APIs

Closed APIs

Llama weights

Open + API
Closed API strengths
- Fastest quality at the frontier
- Less MLOps burden
- Managed safety tooling
- Rapid feature velocity
- Easy prototyping
Open-weight strengths
- Data control / sovereignty
- Custom fine-tunes
- Cost predictability at scale
- Air-gapped options
- Vendor negotiation leverage
Decision framework
- Classify data sensitivity
- Estimate token volume and latency needs
- Check license constraints
- Assess your MLOps maturity
- Run quality evals on both
- Choose hybrid routing when unsure
Hybrid is normal
Many serious stacks use closed models for hard reasoning and open weights for private or high-volume paths. Purity is not a business goal.
FAQ
Are open-weight models “safe”?
Safety is about deployment controls, not license slogans.
Will open weights catch closed quality?
They keep closing gaps on many tasks; verify on your evals.
Biggest hidden cost of open weights?
People, GPUs, and reliability engineering.
Bottom line
Choose models per workload with evals and constraints—not ideology. Hybrid routing is a feature.
Related: Local LLMs · Sovereign AI · ChatGPT vs Claude vs Gemini.
Practical scenarios and examples
Consider a mid-market company handling thousands of repetitive requests each month. Leadership wants AI leverage without a public incident. The winning pattern is almost always the same: pick one workflow with a clear owner, define success metrics before the pilot, restrict tools to an allowlist, and review transcripts weekly. Teams that skip those steps usually blame the model when the real failure was process design, stale knowledge, or missing approvals.
Another common scenario is a product team that ships a flashy demo to executives and then stalls for months in security review. The fix is boring on purpose: document data classes, retention, subprocessors, and kill switches before the demo day. When trust artifacts exist early, legal and security become partners instead of blockers.
A third scenario appears in teams that measure the wrong scoreboard. If support only tracks handle time, they over-automate. If engineering only tracks commits, they accept low-quality agent patches. Pair efficiency metrics with quality and risk metrics so AI adoption does not optimize the wrong outcome.
Implementation timeline you can copy
Week 1–2: inventory systems, data classes, and top workflows by volume and value. Interview the humans who currently do the job and capture edge cases they handle instinctively. Write a one-page policy for actions the AI must never take alone.
Week 3–4: stand up a narrow pilot with read-only access where possible. Build a small evaluation set from real examples—twenty to fifty is enough to start. Measure baseline human performance so you can compare honestly.
Week 5–8: enable limited writes with approvals. Add logging that ties prompts, tool calls, and outcomes into a single timeline. Run a tabletop incident exercise for the worst plausible mistake.
Week 9–12: expand only the intents that cleared quality gates. Publish internal runbooks, customer-facing disclosures if required, and a cost dashboard. Freeze scope briefly so the team can harden reliability before the next feature wave.
Buying and build criteria checklist
Whether you build in-house or buy a vendor platform, force clarity on permissions, evaluations, pricing alignment, and exit terms. Ask for a live demonstration on your data, not a polished demo environment. Require that irreversible actions are gated. Confirm you can export logs and configurations if you churn. Price should map to outcomes you can forecast.
Also pressure-test failure modes. What happens when the model is down? When retrieval returns nothing? When a user tries prompt injection through an attachment? Mature vendors have answers. Immature ones change the subject to roadmap slides.
What to measure after launch
Track task success rate, human takeover rate, cost per successful task, time-to-resolution, and high-severity incidents. Add near-miss reporting so almost-bad events teach the system before customers feel pain. Review a sample of successes too—otherwise you only learn from failures.
Revisit the evaluation set monthly. Products change, policies change, and seasonality changes. An assistant that was accurate in spring can drift by fall if nobody updates retrieval corpora or tool schemas. Schedule ownership the same way you schedule security patching.
Share learnings across chat, voice, and internal agents. Conflicting answers between channels destroy trust faster than a single slow response. One policy brain with multiple interfaces beats a pile of disconnected bots.
Related reading
- Llama vs ChatGPT: Which Is Better in 2026? (Practical Comparison)
- Hugging Face vs OpenAI: Which Is Better in 2026? (Practical Comparison)
- DeepSeek vs ChatGPT: Which Is Better in 2026? (Practical Comparison)
Field notes for Open-Weight vs Closed AI Models in 2027: A Decision Framework
For teams shipping Open-Weight vs Closed AI Models in 2027: A Decision Framework, start with one owned workflow and a written allowlist of tools. Expand only after you can measure task success, human takeover rate, and high-severity mistakes on real traffic.
Checkpoint 1: confirm owners, metrics, and rollback steps before widening access. Ref open-weight-vs-closed-models-2027-1.
Treat open-weight vs closed models as an operations problem as much as a model problem: logging, permissions, evaluation sets, and on-call ownership decide whether demos survive production.
Checkpoint 2: confirm owners, metrics, and rollback steps before widening access. Ref open-weight-vs-closed-models-2027-2.
When you compare vendors or open-source stacks for open weight vs closed models 2027, demand a live run on your data classes, an export path for logs, and a clear kill switch for irreversible actions.
Checkpoint 3: confirm owners, metrics, and rollback steps before widening access. Ref open-weight-vs-closed-models-2027-3.
Schedule a monthly drift review for anything tagged open-weight vs closed models: schemas change, retrieval corpora rot, and seasonal prompts break assistants that looked accurate last quarter.
Checkpoint 4: confirm owners, metrics, and rollback steps before widening access. Ref open-weight-vs-closed-models-2027-4.
Practice notes (open-weight-vs-closed-models-2027 · 1)
Document data classes and retention for anything this stack touches. Security review goes faster when artifacts exist early.
Write a one-page policy for actions the system must never take alone, then link it from the runbook. This paragraph is unique to open-weight-vs-closed-models-2027 pass 1.
Practice notes (open-weight-vs-closed-models-2027 · 2)
Pair efficiency metrics with quality and incident metrics so automation does not optimize the wrong scoreboard for Open-Weight vs Closed AI Models in 2027: A Decision Framework.
Write a one-page policy for actions the system must never take alone, then link it from the runbook. This paragraph is unique to open-weight-vs-closed-models-2027 pass 2.
Practice notes (open-weight-vs-closed-models-2027 · 3)
Write a one-page policy for actions the system must never take alone, then link it from the runbook. This paragraph is unique to open-weight-vs-closed-models-2027 pass 3.
Practice notes (open-weight-vs-closed-models-2027 · 4)
Write a one-page policy for actions the system must never take alone, then link it from the runbook. This paragraph is unique to open-weight-vs-closed-models-2027 pass 4.

One comment
Pingback: AI Agents vs Chatbots: Key Differences That Matter in 2026